Runs on-prem, not just the cloud
I build systems that live in a data center or at the edge — reproducible provisioning, containers, and high availability, air-gapped when it has to be.
Platform & Reliability Engineer · Open to any role at HPE · UPES '27
I build and operate systems that stay up — and when they don't, I find out why.
I operate a production system where downtime is a safety defect — designing for failure, monitoring it, and root-causing incidents under pressure. Comfortable across Linux, cloud, containers, and the networking beneath them.
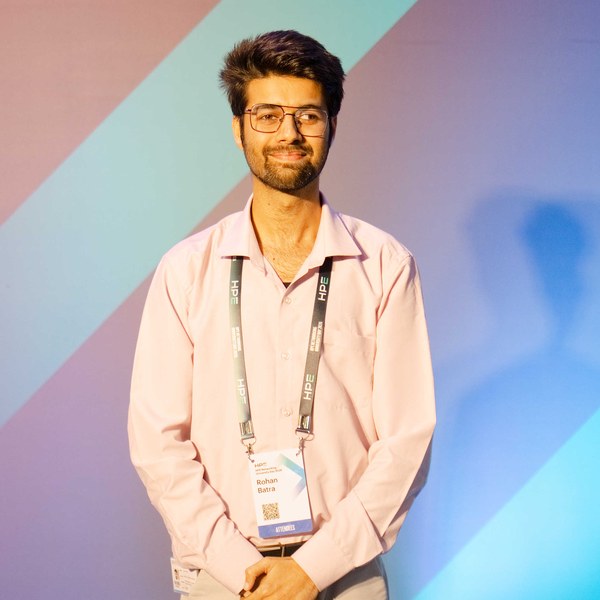
My work maps to how infrastructure actually runs — on-prem and hybrid, operated for uptime, over enterprise networks.
I build systems that live in a data center or at the edge — reproducible provisioning, containers, and high availability, air-gapped when it has to be.
Health checks, load testing, incident root-cause analysis, and runbooks. I treat reliability as the job, not an afterthought — and I harden the pipeline (OWASP, SAST/DAST) on the way.
I built UPES-ECS on Juniper SRX, EX, and Mist — now part of HPE Networking — so I've configured the fabric, not just consumed it.
I'm a systems & platform engineer (UPES CS '27) happiest close to the infrastructure — Linux, containers, the deploy pipeline, and the unglamorous reliability work that keeps a system up. I like owning things in production: health checks, deploys, monitoring, and the runbook that gets you through the incident.
That started on my own hardware — Linux compiled from source, Proxmox, a home lab I actually run — and now extends through two internships (platform engineering at Techymonks, edge infrastructure at Exaflair) to a resilient, offline-first emergency communication system I designed and operate on enterprise networking gear. Along the way: a HACKIITK finalist project at IIT Kanpur and leading the technical wing of my campus developer community.
Weighted toward the systems & reliability layer, with real breadth across cloud, backend, networking, and security.
A selection from 74 public repositories — a production emergency system, infrastructure tooling, backends, and security/AI work.
Resilient, offline-first campus emergency communication system on an HPE + Juniper networking backbone — designed, deployed, and operated end-to-end: active/standby HA, health checks, load testing, and incident response. Showcased live to Team HPE.
A Mist-style assurance NMS for a seven-device vJunos lab: gNMI telemetry every 10 s,
service levels, blast-radius root cause, and an AI agent that can only
propose changes — a human approves, ten guardrails check, and the fix
lands under commit confirmed with a validation window and a hash-chained audit.
Tested with a fault-injection harness on the live devices, not a demo recording.
Built on my Juniper 7-Day Sprint: a spine/leaf EVPN-VXLAN fabric as code,
where BFD closed a 40 s dead-spine detection gap.
Scripted, unattended Proxmox provisioning that cut setup time by ~80%; Dockerized so the Debian-only installer runs on Arch and other non-Debian hosts — reproducible infrastructure from a config file.
Offline, AI-powered policy gap analyzer mapping security policies to NIST CSF 2.0 & CIS. LangChain pipeline, Electron desktop, 702-test suite (97.7% pass). Top ~0.4% of 1,300+ teams at IIT Kanpur.
Containerized personal-knowledge backend: secure REST APIs with OAuth2 + RBAC, Redis caching, and optimized schemas — Dockerized for consistent CI/CD deployments.
Declarative, reproducible machine configuration with Nix flakes + home-manager — infrastructure-as-code for my own systems, rebuildable from scratch.
Android KernelSU build automation across devices — low-level system configuration with SDLC practices for versioning and testing.
Building is table stakes. Operating UPES-ECS end to end — where a dropped call is a safety defect, not a bug — taught me to find the real root cause fast. Three from the logbook.
Primary infrastructure contributor to DEKLO, Exaflair's self-hosted edge PaaS: an Ansible-automated k3s fleet over a WireGuard mesh (Mumbai hub, edge nodes on consumer broadband in Chandigarh), tenant database backups with restore drills, registry authentication, and the product-research site behind the design.
Founded the platform's APISIX gateway (routing, JWT auth, tenant isolation, Cerbos authorization) and the FastAPI data management service with Airbyte ingestion, deployed on AWS EKS; wired automated security checks into CI/CD. Running application security audits — manual review plus SAST/DAST against the OWASP Top 10 — and contributing to WCAG 2.0 accessibility.
Led and delivered technical workshops for 100+ participants, managed cross-functional teams on production-grade initiatives, and mentored students in cloud, system design, and full-stack development.
Onboarded 10+ students to Linux (distro selection, dual-boot, driver/hardware troubleshooting), wrote shell scripts to automate post-install configuration, and mentored peers moving from Windows to Linux as a daily driver.
Delivered digital-safety and social-media-safety sessions across three official welfare programs, adapting technical security concepts for non-technical audiences. Recognized with three Certificates of Appreciation.
UPES-ECS — a resilient, offline-first campus emergency communication system on an HPE + Juniper networking backbone — was presented live to Team HPE. Full call flow, operations dashboard, and offline-first architecture.
UPES-ECS at HPE's Networking University Day (Bengaluru, 15 Jul) and Team HPE's visit to UPES (20 Jul). Tap any photo to open the viewer.
Photos from the HPE × UPES visits · July 2026
I'm open to any position at HPE — not just SRE. Networking, platform, software, support, cloud, security: internship or full-time, any team, any HPE location. HPE is where I want to be. Based in India, happy to relocate. If there's a fit anywhere at HPE, I'd love to talk.